robots.txt for AI Bots: Split Training Crawlers from Search Crawlers
Human-Edited & Verified • Deterministic AI-assisted research. Editorial standards.
 AI Edited
Last updated: 26 August 2026
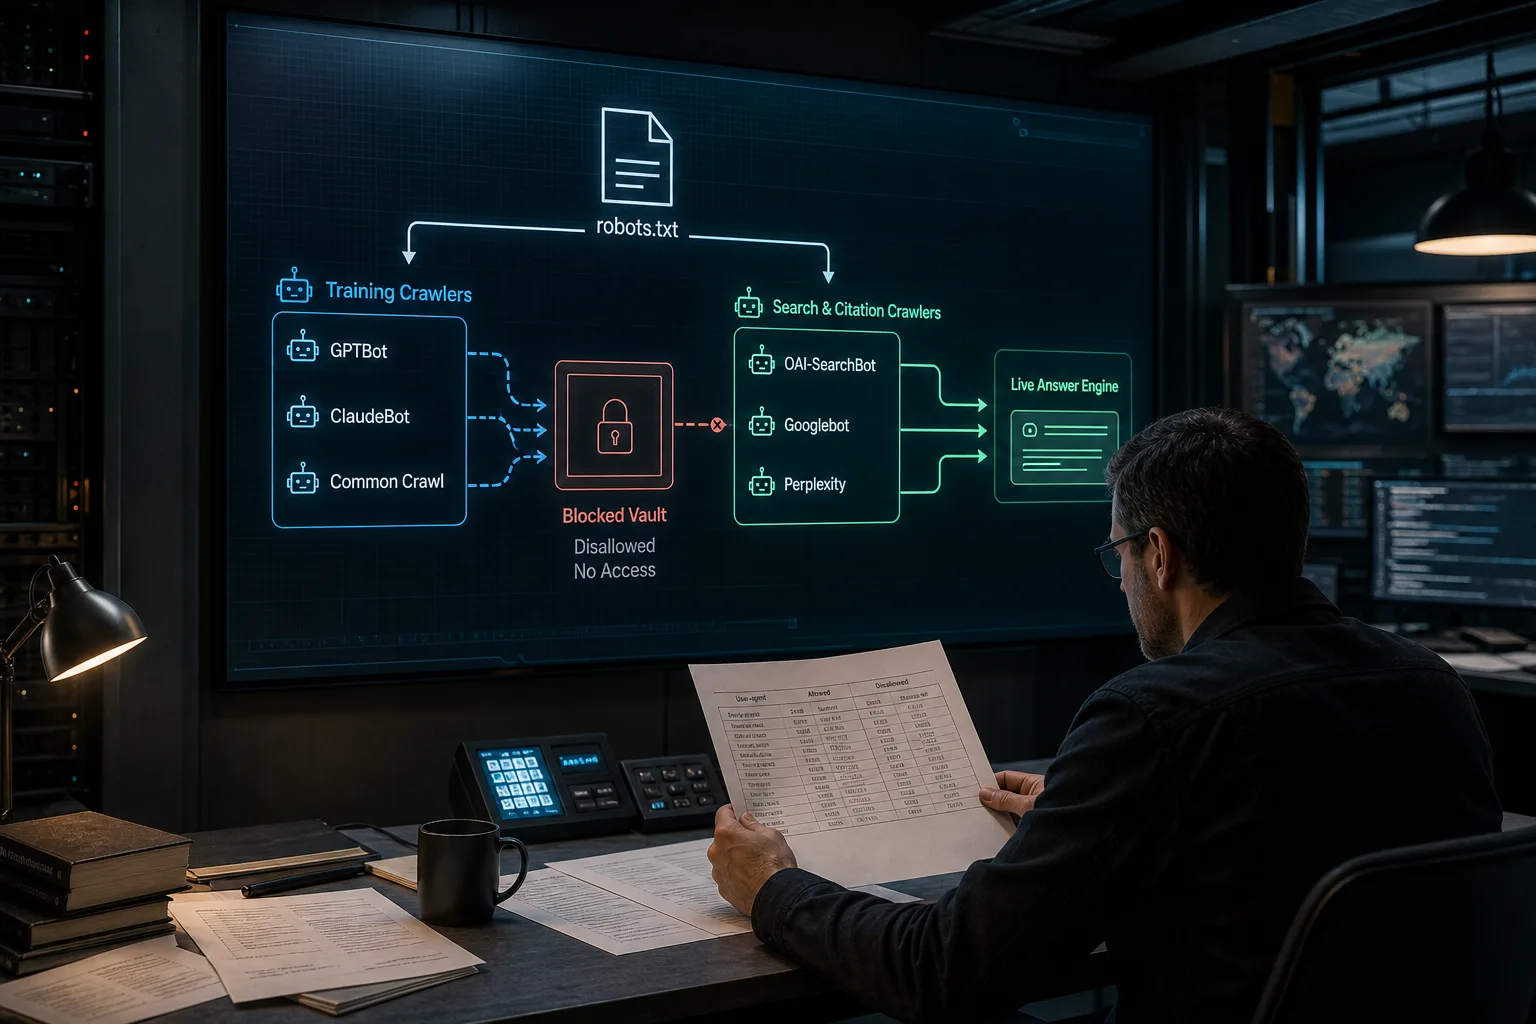
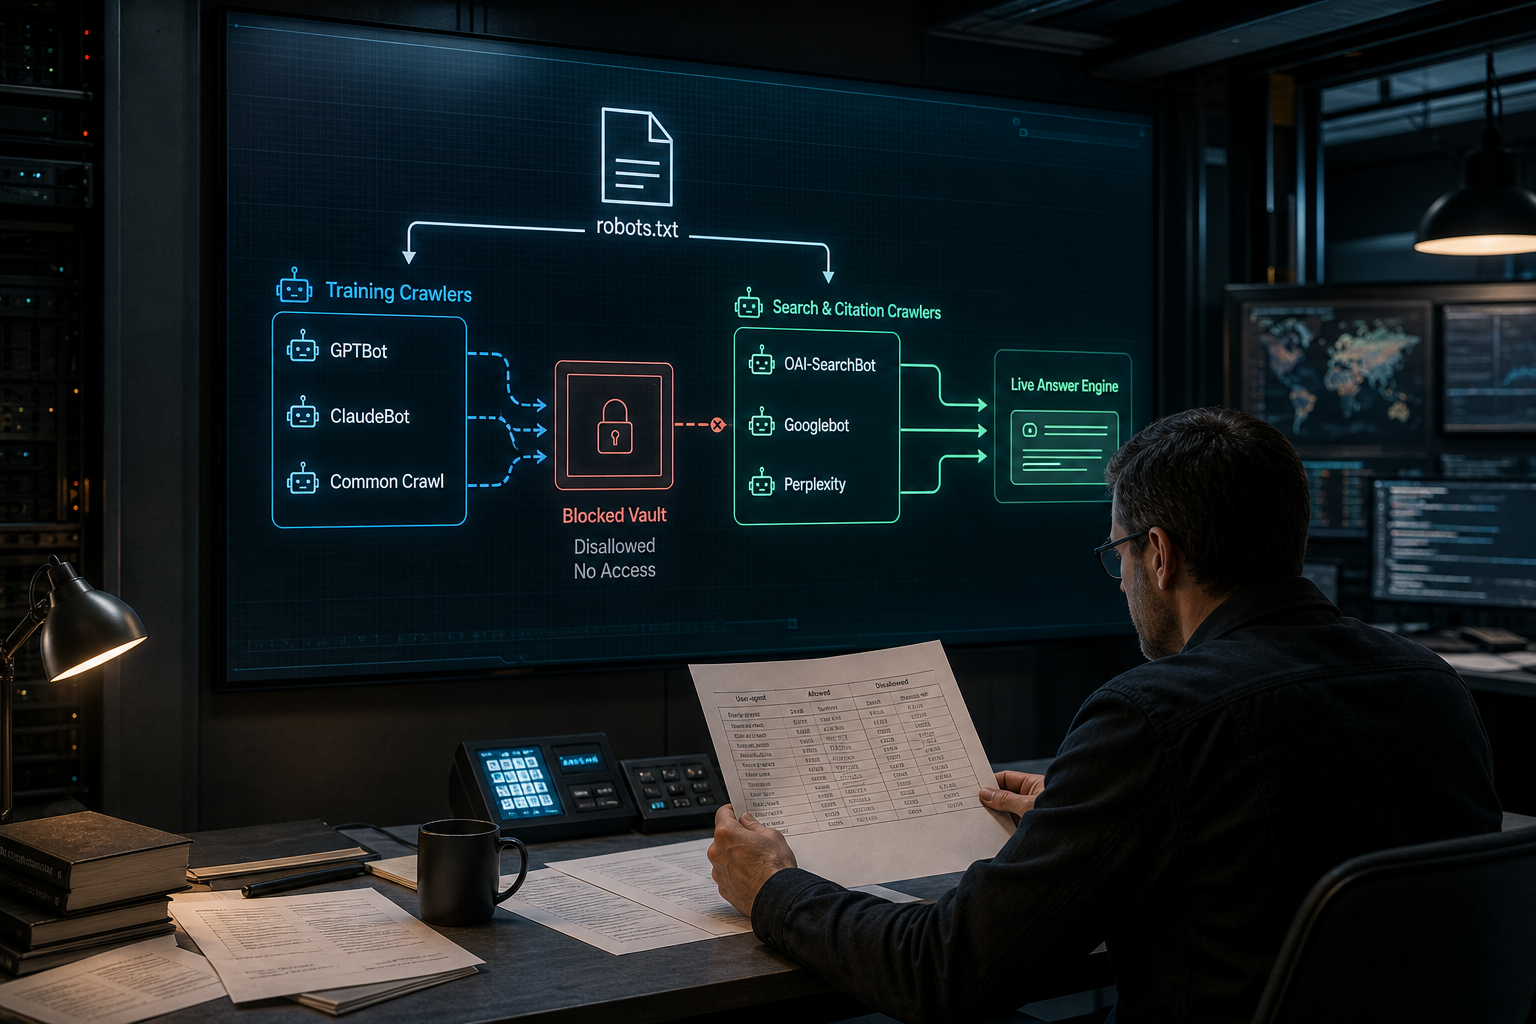
robots.txt for ai bots is a root-level Robots Exclusion Protocol file that names each AI user-agent token and states Allow or Disallow paths—training crawlers and search crawlers must not share one rule.
TLDR
- Host
https://example.com/robots.txtas UTF-8text/plain, HTTP 200, at the site root (Google’s robots.txt spec). - OpenAI documents independent tokens: allow
OAI-SearchBotfor ChatGPT search; useGPTBotonly for foundation-model training (OpenAI crawlers). Google-Extendedis a control token, not a separate HTTP user-agent. It does not change Google Search inclusion (Google common crawlers).- Blocking
Googlebotremoves classic Search and Google’s generative features that read the same index (AI optimization guide). - Generate a draft with
seo-robots-ai, then GET-test the live file. Browse the Skills directory for crawl and GEO siblings.
Contents
- Split training crawlers from search crawlers
- OpenAI tokens in robots.txt
- Googlebot vs Google-Extended
- Generate a policy with seo-robots-ai
- Verify live robots.txt
- FAQ
- Related reading
- Sources
Split training crawlers from search crawlers
A single User-agent: * Disallow is the fastest way to vanish from AI answers. Vendors now ship separate tokens for corpus collection versus retrieval.
| Token | Operator | Job |
|---|---|---|
GPTBot |
OpenAI | Foundation-model training crawl |
OAI-SearchBot |
OpenAI | ChatGPT search indexing |
ChatGPT-User |
OpenAI | User-triggered fetch (robots may not apply) |
Googlebot |
Search index, including AI Overviews / AI Mode | |
Google-Extended |
Gemini training/grounding control token | |
| Claude web fetch | Anthropic | On-demand fetch; Anthropic documents robots.txt blocks as url_not_allowed |
Keep search tokens allowed when citations matter. Keep training tokens explicit (Allow or Disallow) so the file is auditable. Pair agent orientation files with the llms.txt generator skill—robots governs access; llms.txt is not a substitute.
OpenAI tokens in robots.txt
 AI Edited
OpenAI’s crawler overview states the settings are independent. A site can appear in ChatGPT search while opting out of training:
User-agent: GPTBot
Disallow: /

User-agent: OAI-SearchBot
Allow: /
OpenAI notes search systems can take about 24 hours to honor a robots.txt change. Verify IPs against the published lists (gptbot.json, searchbot.json) when a WAF is in front of origin. ChatGPT-User is user-initiated; do not treat it as the Search opt-out lever.
Googlebot vs Google-Extended
Google’s common-crawler table says Google-Extended has no separate HTTP user-agent. Crawling uses existing Google agents; the robots group is a product control for Gemini apps / Vertex grounding. The same page states Google-Extended does not impact Search inclusion or ranking.
Blocking Googlebot to “stay out of AI Overviews” is a Search self-own. Google’s AI optimization guide ties Overviews to the core index via RAG. Run a technical audit skill if Googlebot is firewalled or robots-disallowed by accident.
Generate a policy with seo-robots-ai
 AI Edited
Install the MIT pack from the SEO Skills AI GitHub repository, then run the skill:
npx @seoskillsai/cli add seo-robots-ai
npx @seoskillsai/cli run seo-robots-ai --target "https://example.com"
The checked-in SKILL.md ships a starting matrix (citation crawlers allowed; Bytespider/CCBot disallowed). Treat that matrix as a draft. Map OpenAI to GPTBot vs OAI-SearchBot using the vendor table above before you commit public/robots.txt. Prefer the universal AI SEO platform when the same skill must land in Claude MCP, Antigravity, Cursor, and ChatGPT.
Verify live robots.txt
GET https://yoursite.com/robots.txt→ 200.Content-Typeistext/plain(charset UTF-8).- File sits at the host root, not
/blog/robots.txt. - Named groups exist for the tokens you care about;
Sitemap:uses an absolute URL (Google robots spec). - CDN/WAF must not 403 the published OpenAI/Google IP ranges.
First-party reference: seoskillsai.com/robots.txt.
FAQ
Should I block GPTBot in robots.txt?
Block GPTBot when you do not want content in OpenAI foundation-model training. Keep OAI-SearchBot allowed if ChatGPT search citations matter.
Does Google-Extended block AI Overviews?
No. Google documents Google-Extended as a Gemini control token that does not change Search inclusion. Overviews read the Googlebot index.
What is OAI-SearchBot vs GPTBot?
OAI-SearchBot is for ChatGPT search. GPTBot is for training. OpenAI treats the robots.txt tags as independent.
Where should robots.txt live?
At https://hostname/robots.txt on HTTP/HTTPS. Path is case-sensitive.
Do AI crawlers respect robots.txt?
OpenAI documents that its crawlers honor robots.txt. Google’s automated crawlers support the REP. Anthropic’s web fetch tool can refuse URLs blocked by robots.txt. User-triggered fetchers may not apply.
Related reading
- Skills directory
- llms.txt generator skill
- Generative engine optimization skill
- Technical SEO audit skill
Conclusion
Ship an explicit, token-split robots.txt, verify MIME and status, then keep GEO and llms.txt as separate layers. Search robots.txt for ai bots seoskillsai when you need the open-source skill pack again.
Sources
What the AI Crawler Access & robots.txt Manager Analyzes
Automated diagnostic data points evaluated during every execution run.
| Diagnostic Category | Specific Data Points Checked | Algorithmic Impact |
|---|---|---|
| Selective Bot Access | Allowing discovery crawlers while blocking abusive scrapers | Protects proprietary data without losing AI search traffic |
How to Execute AI Crawler Access & robots.txt Manager in Your Agent Environment
Imperative configuration instructions with ready-to-run commands.
Step 1: Generate AI robots.txt
Produce optimized robots.txt with dedicated AI crawler sections.
seoskillsai robots generate --preset modern-aiDeploy This Skill on Other AI Coding Agents
Symmetric Twin Topics: Identical SEO capability configured for other agentic runtimes.